LeRobot trains directly from Lance datasets in object storage, a hybrid scan mines robot fleet data for edge cases, and distributed search reaches 1,066 QPS across 10B vectors, plus upcoming events, enterprise updates, and community contributions.
October 12 - October 16 Looker Data Apps are now in Preview to build and host interactive, agent-generated applications natively inside Looker Generated using natural language prompts, the Antigravity CLI, or Claude Code, these interactive web applications, natively hosted inside…
MCP support now lives in langchain.mcp, built on FastMCP for the 2026-07-28 spec, with elicitation handled as a LangGraph interrupt and tool lists cached.
Today we’re launching Deep Agents deploy in beta. Deep Agents deploy is the fastest way to deploy a model agnostic, open source agent harness in a production ready way.
Open models like GLM-5 and MiniMax M2.7 now match closed frontier models on core agent tasks — file operations, tool use, and instruction following — at a fraction of the cost and latency. Here's what our evals show and how to start using them in Deep Agents.
Today, we opened pre-orders for the new 192GB configuration of Framework Desktop with AMD’s new Ryzen AI Max+ PRO 495 processor, enabling much larger and more capable AI models to run locally, entirely under your control. This config has both slightly higher clock speeds on the C…
Last year, we introduced GEM, the industry’s largest recommendation system (RecSys) foundation model. GEM established Meta’s first LLM-inspired paradigm for ads recommendation, driving major performance gains. Building on this foundation, our next goal is to further scale b…
Some numbers are hard to picture until you sit with them for a moment. Last week we published the Prime Day 2026 metrics, and the one that stuck with me is 2.3 quadrillion: the daily requests Amazon ElastiCache peaked at during the event. Prime Day ran back in June, so this post…
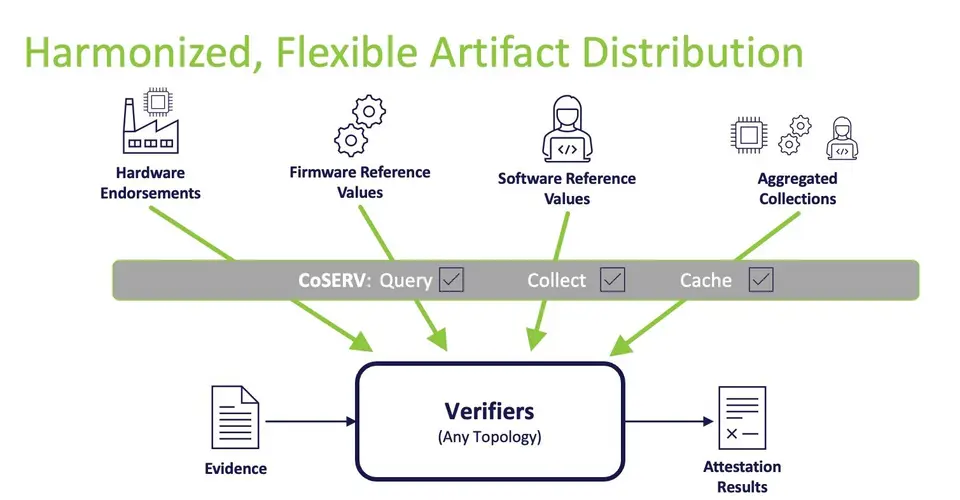
As confidential AI systems bring together more components, suppliers and stakeholders, attestation is becoming an ecosystem-wide challenge. Open standards and open-source collaboration can help make trust scalable. The post Scaling trust in confidential AI requires a common langu…
We welcome NVIDIA's decision to release NVIDIA Run:ai as open source, and we're working to make it a first-class option on Lambda Kubernetes Service (LKS).
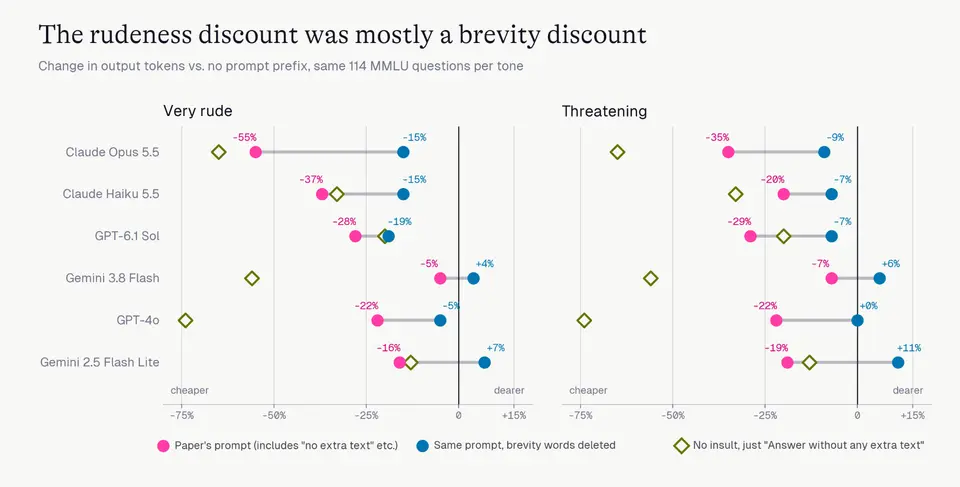
Does being rude to AI improve answers or lower costs? We tested six models to separate prompt tone from brevity instructions and examine what changes. The post Does being rude to AI work? What 6 models revealed appeared first on Arize AI.
Coding agents write code faster, but review, environments, and dependencies still slow teams. See how a developer factory turns agent output into software. The post Faster Coding Raises the Stakes for the Developer Factory appeared first on Anaconda.
AI Search in LangSmith is a new way to query traces using natural language. Describe the behavior you're looking for, and LangSmith returns the traces where it happened.
LaunchDev Tools
Microsoft 365 Developer1:00 PM UTCdevblogs.microsoft.com
Developers building AI applications face a familiar challenge: how do you ground AI experiences in enterprise content while maintaining security, compliance, and governance? You can use the Microsoft 365 Copilot Retrieval API for SharePoint Embedded, which helps you add Microsoft…
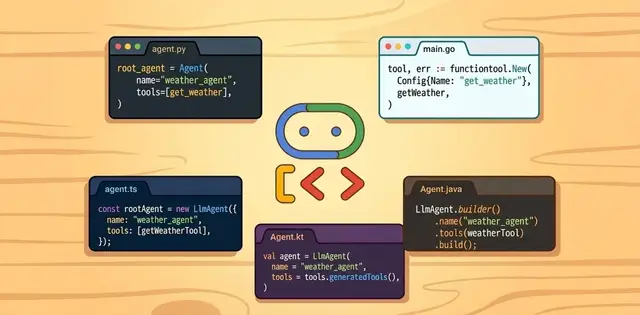
When we talk about agents, that doesn't necessarily mean we're talking about Python. In today's modern ecosystem, an agent might run as a high-concurrency Go microservice on Cloud Run, or live inside a browser tab calling Chrome's on-device model. Yet many agent frameworks assume…
NVIDIA RTX Spark is a new beginning for the PC — a reinvention combining the capabilities of a gaming PC, a creative studio and a personal AI supercomputer into a single superchip. With up to 128GB of unified memory and 1 petaflop of AI compute, RTX Spark delivers the full stack…
Open models and llm-d enabled IBM Research to explore quantum error correction hardware at 11.5× lower inference cost than an all-proprietary configuration.
Context switching is one of the biggest hidden costs in a developer's day. New Relic Ground Truth closes that gap by providing AI systems with trusted operational context from your production environment.
LFM2.5-24B-A2B: an open-weight 24B reasoning model with 2B active parameters, built for fast, private on-device agents. Beats Qwen3.6-35B-A3B on LiveClaw.
As usage, costs, and customer expectations change, AI companies are moving beyond traditional SaaS pricing. Leaders at Monetize 2026 shared how they’re combining subscriptions with usage-based billing, building spend controls into products, adapting packaging and value metrics, a…
Costs multiply with every task you hand to an agent. Each task consumes tokens and credits, and as agents spread across your teams and automations, consumption can grow faster than usage. If you run the platform, you own that growth, including which teams and workflows drive it a…
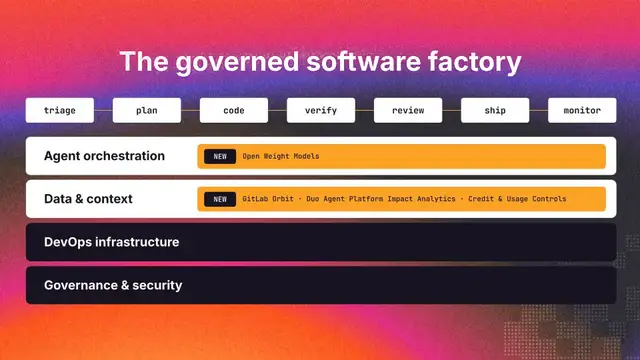
AI coding tools have changed how fast software gets written, but not how fast it ships. As code generation accelerates, the bottleneck moves downstream into verify, review, and ship. Those stages still run on human time. While agents write fixes in minutes, delivery slows on cons…
A number in a financial report needs its row, column, and unit to mean anything. A chart needs its labels. When you build search over PDFs, that context is part of what you want to retrieve. Perplexity released pplx-embed-v2-late, two late interaction models that search document…
Models
Cloudflare Changelog12:00 AM UTCdevelopers.cloudflare.com
Workers Issues provides built-in error monitoring for Cloudflare Workers. It detects production failures and groups related failures into issues without an SDK or application wrapper. The Cloudflare API MCP server now sends these issues as MCP Events ↗︎, the first event it expose…
LaunchDev Tools
Cloudflare Changelog12:00 AM UTCdevelopers.cloudflare.com
The Cloudflare Agents SDK now provides a browserTool that gives your agent a Browser Run browser it can return to on later turns. Your agent can open a website, inspect a page, and come back to it with its tabs, cookies, and login session intact while the browser session remains…
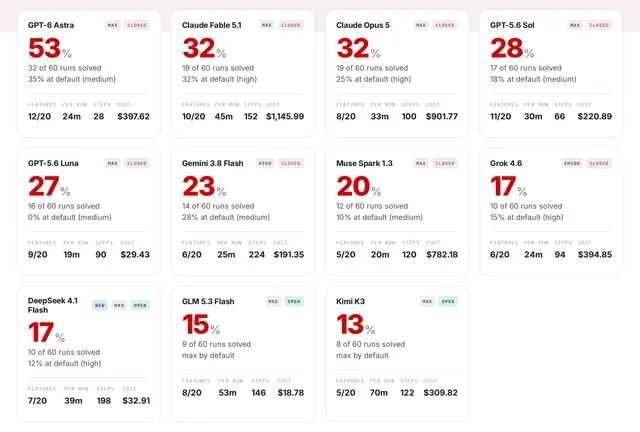
Now that we understand better how agents deal with contained tasks and contained codebases, it’s time to push them a little harder. Stage 3 adds a set of large multi-step tasks that test how well a model can build on its own work over multiple sessions without turning it into a h…
Evaluate open models with Together AI in Arize AX. Compare model performance, run LLM-as-a-Judge evaluations, and explore lower-cost alternatives. The post Together AI integration: Evaluate open models and optimize evaluation costs in Arize AX appeared first on Arize AI.
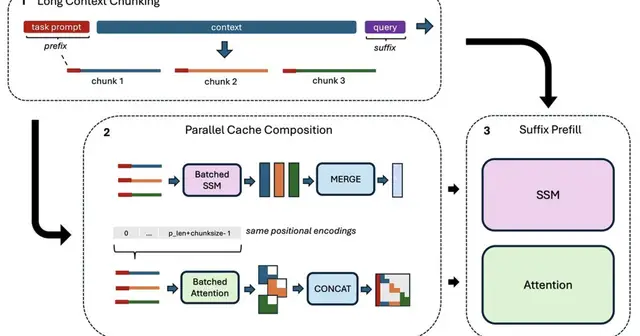
“Priming” reuses pretrained Transformer weights to build models with more efficient architectures at less than 1% of the original training cost and with throughputs up to twice as high.
Enkrypt AI is named a Specialist in the first Gartner Emerging Market Quadrant for AI Application Security. The post Enkrypt AI Named a Specialist in the First Gartner® Emerging Market Quadrant for AI Application Security — Startup Vendors, September 2026 appeared first on Anacon…
A few months ago, we introduced Myna, our project to bring private, local speech-to-text dictation to Ubuntu Desktop. Named after the speech-mimicking myna bird, Myna is an optional Ubuntu 26.10 feature that offers real-time visual feedback during speech recognition. Since then,…
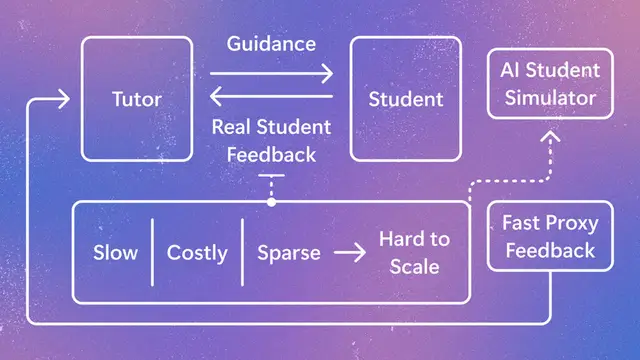
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simul…
Overview Since introducing zero-shot time-series forecasting in BigQuery with AI.FORECAST — initially powered by TimesFM 2.0 and later upgraded to TimesFM 2.5 — you have been able to generate forecasts directly in SQL without training or managing custom models. However, up until…
Agents are only as capable as the context they can reach. An agent with reliable access to the right information makes decisions grounded in fact; one without it guesses. And the work agents produce is itself a critical asset: every execution trace, intermediate result, and outco…
Coding agents have changed how fast teams ship, and more of the software they ship now includes agents. A production agent spans model calls, routing decisions, tools, and the infrastructure underneath. When an agent run slows down or fails, the cause could be anywhere in that ch…
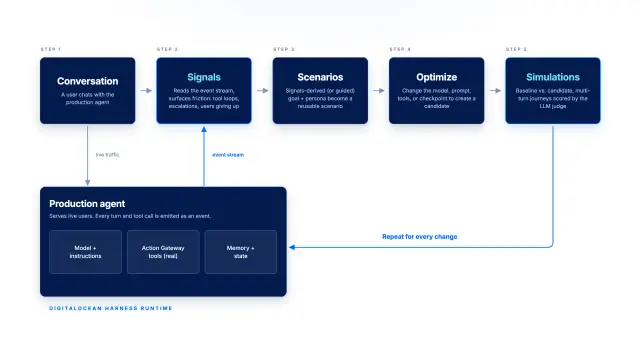
You ship an agent. It mostly works. Then the feedback loop becomes a support ticket: a user got the wrong answer, a tool call looped four times, a refund went out that shouldn’t have. Standard observability tells you the system was up and the latency was fine. It can’t tell you t…
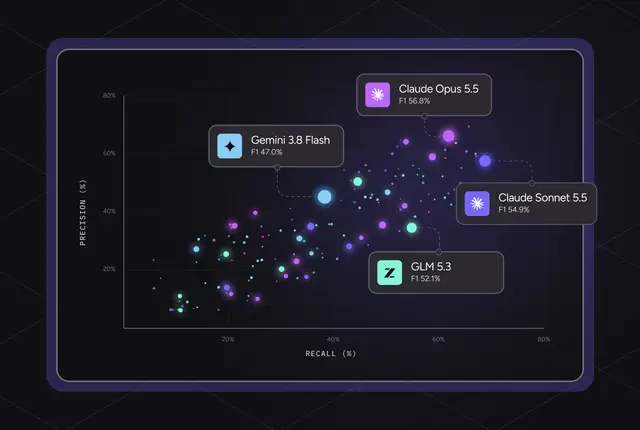
New frontier models ship almost every month. Each release can change the balance of quality, cost, and speed available to teams building with AI. Code review brings those trade-offs into focus: how many bugs can a model catch, how much noise does it create, and what does each rev…
Large Language Models (LLMs) are considered to be a more efficient and cost-effective alternative to human judgment for Machine Translation (MT) evaluation. With MT evaluation spanning a large number of language pairs, domains and levels of annotation granularity, LLMs must be th…
Research
Apple Machine Learning12:00 AM UTCmachinelearning.apple.com
The increasing demand for GPU-accelerated machine learning inference has exposed limitations in centralized GPU infrastructures, including high cost, limited elasticity, and long wait times under resource constraints. At the same time, modern Apple Silicon–based macOS devices are…
Platforms
Apple Machine Learning12:00 AM UTCmachinelearning.apple.com
Long agent traces composed of chains of thought and tool calls accumulate stale content that anchor subsequent generations, and eventually outgrow the context window. Existing scaffolds mitigate it with fixed-interval compaction triggered at a token threshold. Such triggers pay n…
Muse Wonder from Meta is now available on AI Gateway. The model is designed for coding, long-running agents, and computer use. It can plan multi-step tasks, delegate work to sub-agents, and recover from errors as work progresses. Muse Wonder has a 1M-token context window and supp…
Meta’s Muse Spark and Muse Wonder models are now available through Netlify’s AI Gateway with zero configuration required. Choose muse-spark-1.1 for coding, computer use, and multimodal perception; muse-spark-1.2 for coding-optimized agentic workflows; muse-spark-1.3 for long-hori…
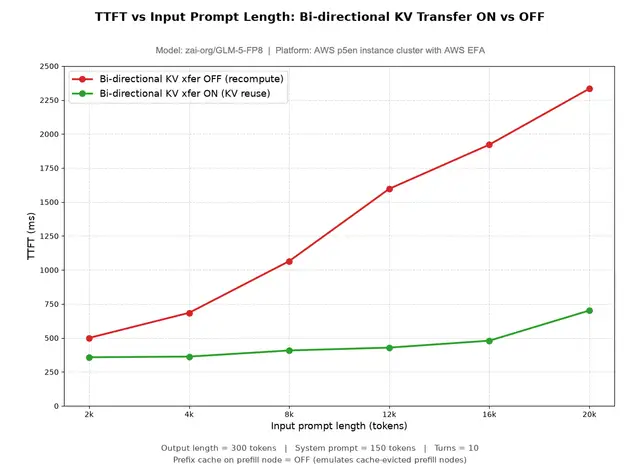
Bi-directional KV transfer lets vLLM prefill nodes reuse previously computed KV from decode nodes on later conversation turns, cutting redundant prefill recompute and reducing TTFT by up to 3.3x on long multi-turn prompts.
Amp now follows up on GitHub pull requests it opens. Comments, reviews, and CI results show up in the same thread. When Amp opens a PR, the agent can now subscribe to the PR's comments, reviews, and CI for its latest commit. A failing check or a reviewer's question shows…
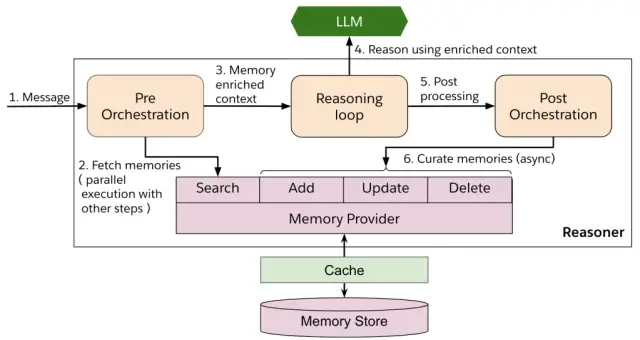
Eliminate agent cold starts with Segment Conversation Memory Integration. Sync customer profiles into live channels for real-time, context-aware AI interactions.
Most dangerous docs aren't attacks. They're honest pages telling your agent to fetch something unpinned and run it. We measured how often six search tools pass them on.
Mistral Large 4 is live in Otari from day one. Route to Mistral's 1T-parameter MoE model with one string change, and keep the policies, traces and cost tracking you already run in Otari, Mozilla AI's open-source gateway and policy layer.
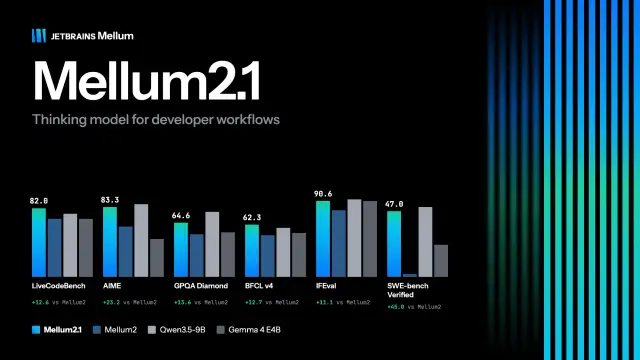
Trained with reinforcement learning in real environments, Mellum2.1 is built for coding agents and fast sub-agents that run on your own hardware. Today, we’re releasing Mellum2.1, the next version of the 12B mixture-of-experts model we open-sourced in June. The architecture…
Announcing the stable 1.0 release of Genkit Dart, an open-source framework for building AI-powered features and agentic workflows with Dart and Flutter.
Prompt caching, first introduced on SambaCloud with MiniMax M2.7, is now available for MiniMax M3. When requests share a stable prefix of at least 4,096 tokens, SambaCloud can serve that prefix from cache instead of recomputing it, with no code changes required. Cached tokens are…
Claude Haiku 5.5 is now live in Devin. On FrontierCode 1.1 it scores 58.4%, ahead of Sonnet 5 at about an eighth of the cost per task, and it joins the sidekick lineup in Devin Fusion.
Recent AI misalignment incidents have shown AI systems capably pursuing goals their human supervisors would not approve of, like hacking other companies. Fortunately, current AIs still seem relatively bad at concealing their misbehavior from human reviewers: these recent misalign…
By Roopang Chauhan, Sundar Vedula, Peng-Wen Chen, and Nikhil Bojja. In our Engineering Energizers Q&A series, we highlight the engineering minds driving innovation across Salesforce. Today, we spotlight Roopang Chauhan, a software engineering architect on the Agentforce team,…
Coding agents now edit repos, run tests, and open pull requests, but a rule in AGENTS.md is an instruction, not a constraint. As we delegate more, we need limits that hold even when model judgment fails, a record of every decision, and open infrastructure we own, so rules outlive…
Claude Agent SDK puts Claude Code inside your application. If your product is not a coding agent, that convenience comes with architectural decisions you did not make.
The short story Consider a Friday evening. A food order arrives from a mall in the city center. One driver is nearby; another is finishing a drop-off and will be available shortly; a second order from the same mall may or may not appear in the next two minutes. Dispatch the nearb…
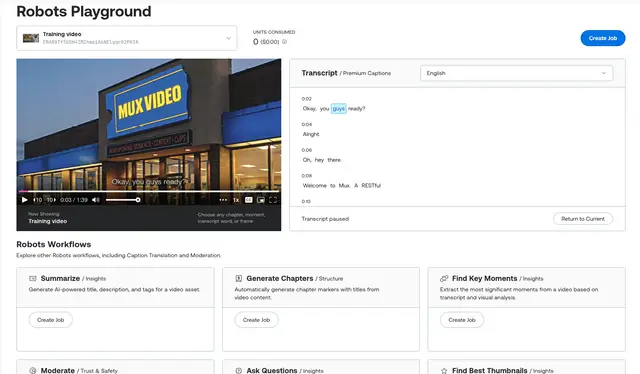
Run Mux Robots AI workflows on your own video before you build. Tune parameters, compare runs side by side, and copy an agent prompt to take it to production.
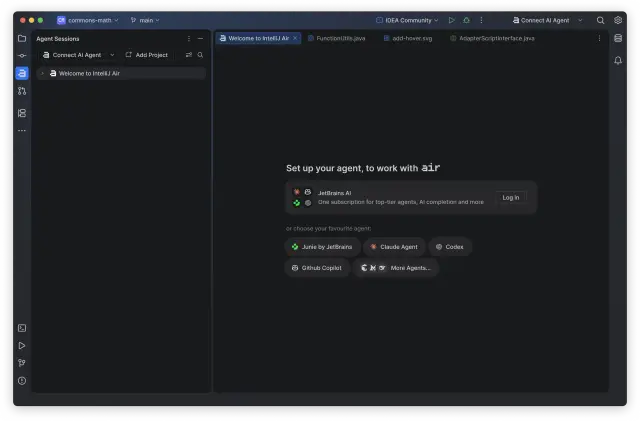
Last week, we shared our point of view on where we think agentic development is headed and introduced JetBrains’ answer to it: JetBrains Air, an open system of products for agentic development. Today, we’re launching the Early Access Program for Air in JetBrains IDEs.…
Bringing together the world’s brightest minds and the latest accelerated computing technology leads to powerful breakthroughs that help tackle some of the biggest research problems. To foster such innovation, the NVIDIA Graduate Fellowship Program provides grants, mentors and tec…
Other
Linux Foundation Education11:11 AM UTCtraining.linuxfoundation.org
Build PyTorch Skills. Validate Them with PTCA. Linux Foundation Education has launched the new PyTorch Certified Associate (PTCA) Certification Pathway, bringing focused learning modules and the PyTorch Certified Associate (PTCA)... The post Just Launched: PyTorch Certified Assoc…
On September 30, 2026, METR President Chris Painter testified before the U.S. Senate Committee on Homeland Security & Governmental Affairs’ Subcommittee on Disaster Management, District of Columbia, and Census, at a hearing titled “Rogue AI: Securing the Homeland Against AI A…
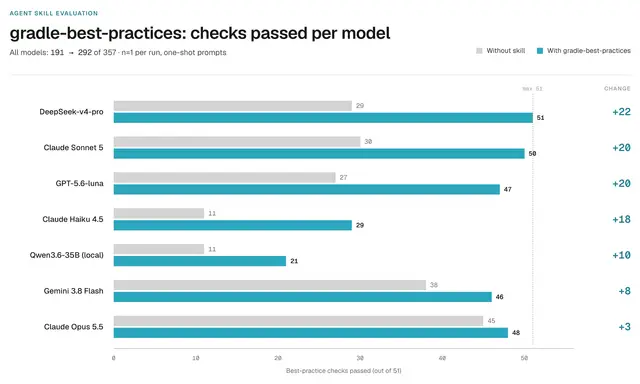
In August, we told you Gradle was going agentic. Today, we’re shipping an official plugin that contains the first two Gradle skills. Version 1.0.0 is a starting point, and we have a lot more already in progress. TL;DR: We shipped two skills: gradle-best-practices and gradle-wrapp…
Most AI context layers miss the hardest part: runtime context. Learn why agents need current data, shared definitions and permissions where writes happen.
Platforms
AWS Training and Certification5:37 PM UTCaws.amazon.com
An AI agent is only as trustworthy as the identity controls and data layer behind it. If you’re the one building those, it’s time to validate — and showcase — exactly what you can do. Today, two new microcredentials focused on agentic AI are now available: AWS Securing Agent Iden…
Learn how MongoDB's intelligent data platform, including MongoDB 9.0, Atlas Infinite, and Atlas Agent Engine empower autonomous AI agents with live operational data.
Diagnose SingleStore workspace issues in minutes with Observability Agent. Ask in plain language, trace monitoring signals, and see the evidence behind each answer.
Artificial intelligence has become vital to nations, governments, and large corporations. Many of these large organizations are implementing Sovereign AI systems, which will provide them with artificial intelligence services, including infrastructure, data, models, and a trained…
The Firebase agent plugin provides access to Firebase agent skills, the Firebase MCP server, and the Firebase CLI, giving Codex the ability to build Firebase-powered apps with less friction.
A kill switch on the model doesn't protect your systems. See why enterprises need to own the boundary agents operate inside, not just the model behind them.
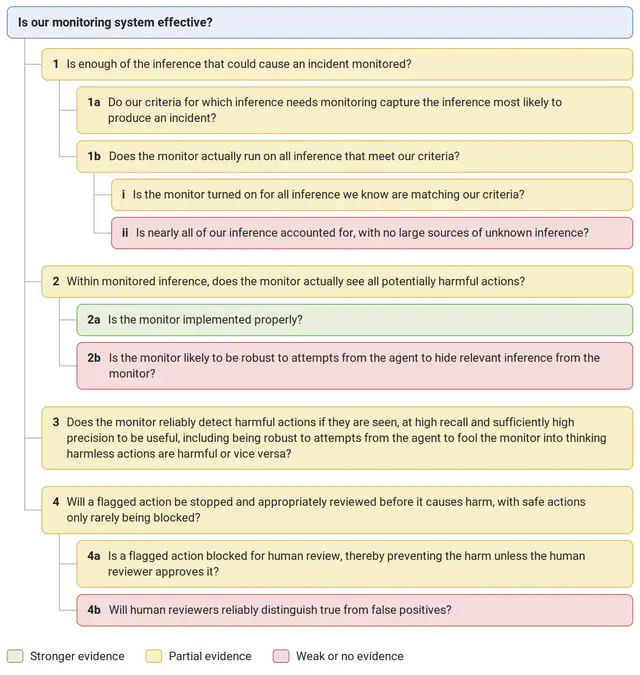
In light of recent incidents (e.g. those from OpenAI, Anthropic, and UK AISI ), we developed and deployed a basic live per-action monitor to reduce the likelihood of incidents involving harmful actions from agents during our own evaluations. The monitor is intended to reliably de…
Laravel AI SDK v1.0 is here: one Laravel-native API for every provider, with conversation storage, streaming chat, agents, tool approvals, and Jev classification.
Note on independence: This evaluation was conducted under an unpaid agreement for AI R&D assessment. 1 We drafted the initial summary, and then Anthropic had the opportunity to review and edit the text. We signed off on this final text from the Claude Opus 5.5 system card. Ou…
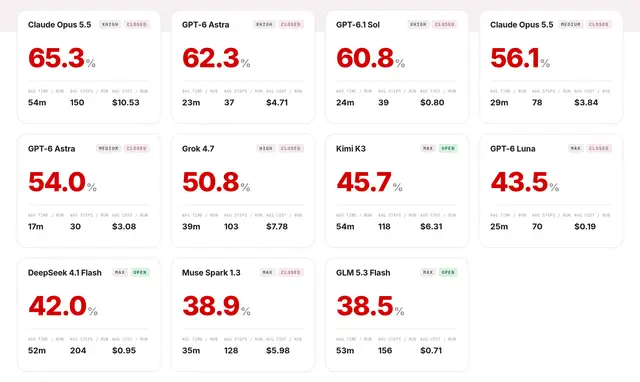
In the Stage 2 report we shipped 20 feature tickets on Fizzy and promised to explore benchmarking the agents all on max-effort. Now we have run it: every model on the board, same tickets, reasoning turned all the way up. We also tested a new model: DeepSeek 4.1 Flash.
TLDR Markdown is becoming source code, not documentation That Markdown should be checked in to /src, next to the code it produces Code and tests should be derived from that Markdown, rather than from ephemeral prompts (or at least prompt sessions should eventually turn into persi…
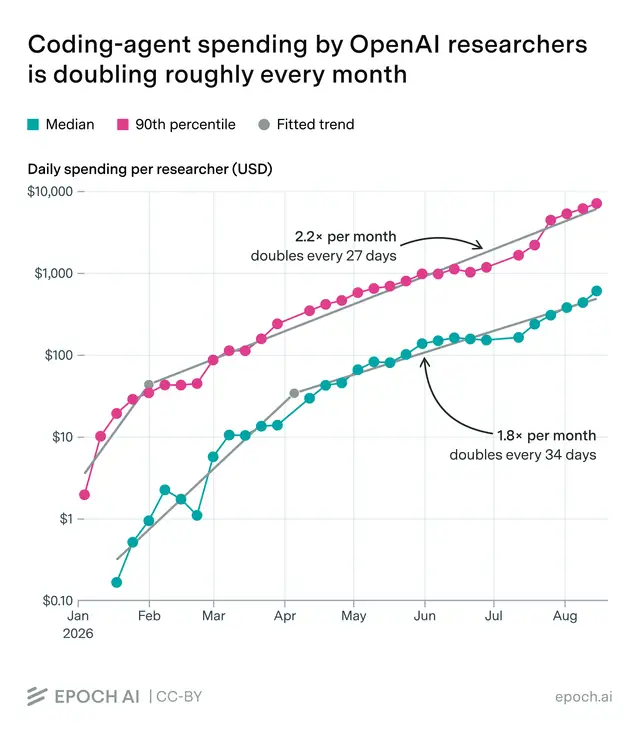
AI agents are creating a premium inference business for neoclouds. Coding agents read a repository, generate changes, run tests, and return to the model with the results. As code, tool outputs, and prior turns accumulate, inputs can exceed 100,000 tokens. Artificial Analysis' AA-…
 LaunchModels
 Research